NodeQuartz Consulting

Programming consulting focused on production software troubleshooting — log triage, failing deployments, and brittle integrations that only surface under real traffic.

+27-44-000-0120 · Knysna, Western Cape

Supplier details (ECT Act s43): NodeQuartz Consulting (Pty) Ltd, a private company incorporated in South Africa. CIPC registration 2018/894680/07. Physical address: 8, Main Road, 6571 Knysna, South Africa. Contact: +27-44-000-0120, info@nodequartz.digital. Director: Nomsa van der Merwe.

Checklist before you escalate a production fault

Use this as a sanity pass when on-call noise outpaces signal. We walk through the same items on assessment calls.

Capture the failing boundary

Note the service name, region, build ID, and whether the fault is user-visible or background-only. Screenshots of dashboards beat paraphrased summaries.

  • Error rate spike with flat CPU?
  • Recent config or feature flag change?
  • Dependency timeout pattern in traces?
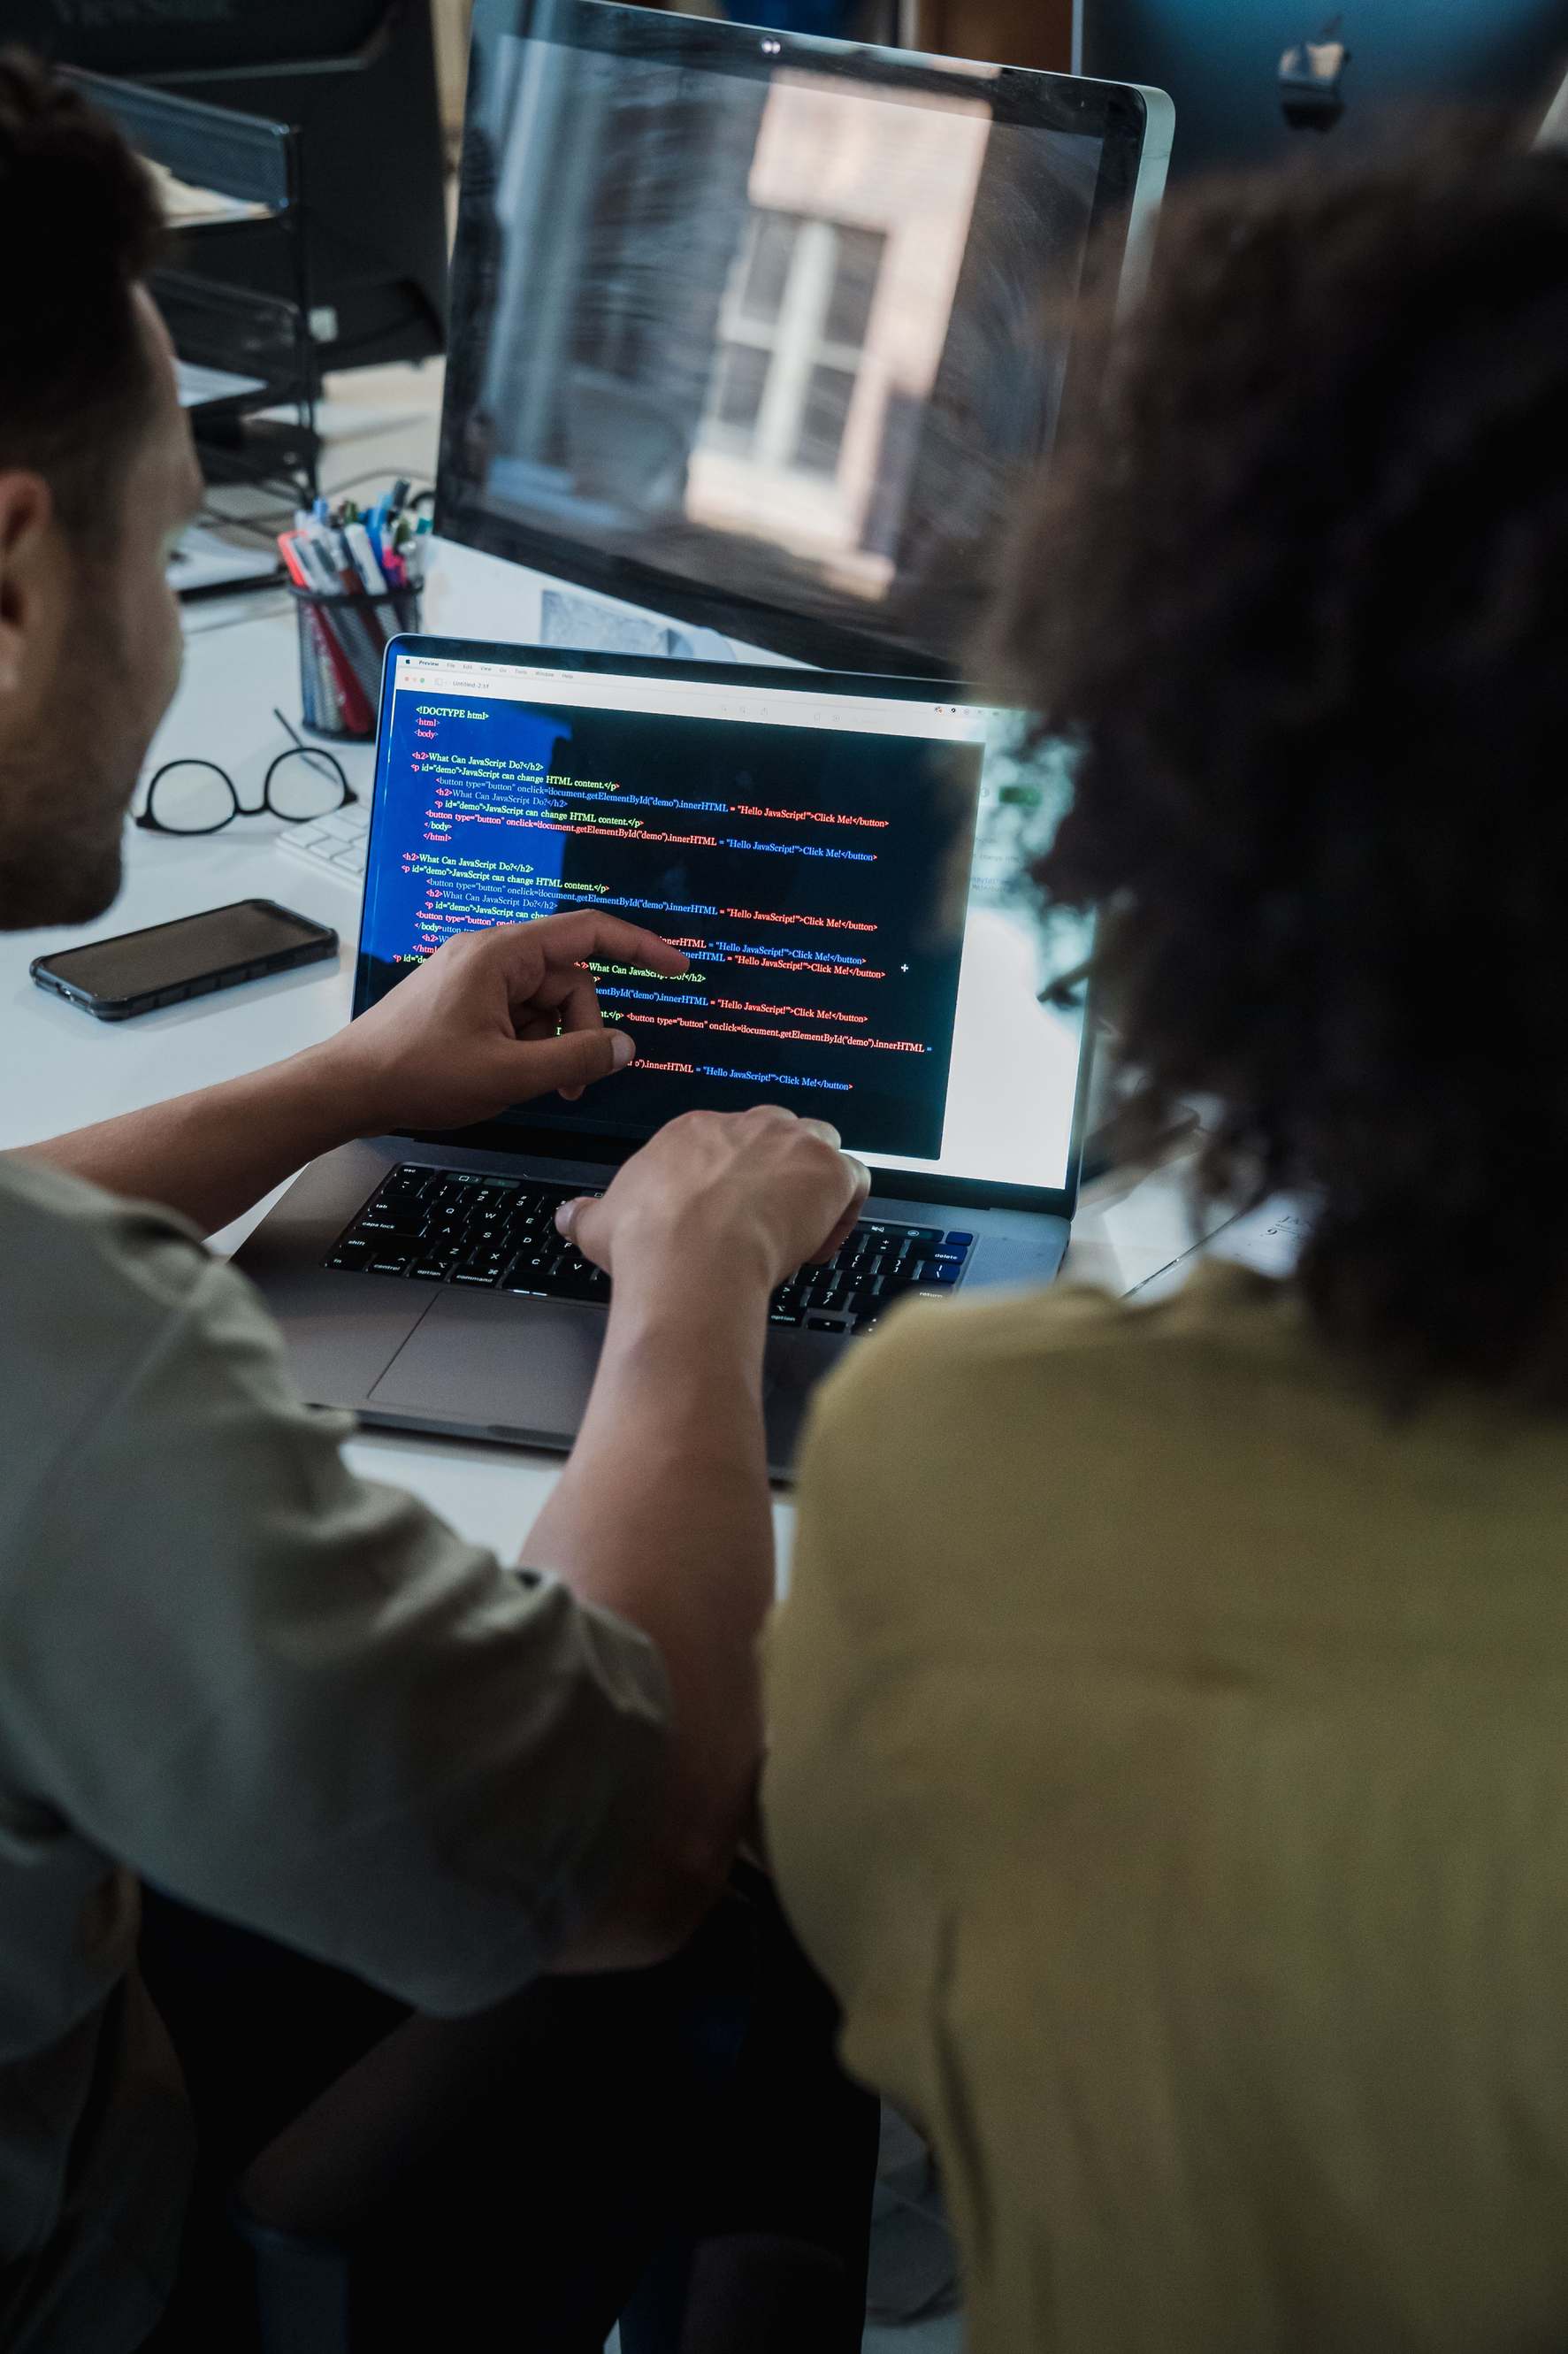
Laptop showing source code during a debugging session in an office
Server rack with network cables in a data environment

Stabilise before root cause

Rollback, traffic shed, or circuit-break where policy allows. Document what you changed so a later fix does not fight a hidden mitigation.

How we scope programming consulting work

Fees and deliverables are agreed after inquiry — no fixed product tiers. These are the engagement shapes we most often run for production troubleshooting.

Technical assessment

Time-boxed review of repositories, CI/CD paths, observability, and incident timelines. You receive a written findings memo with ranked risks and suggested experiments — not a slide deck of buzzwords.

Typical starting point when leadership needs an independent read before funding a larger fix.
Advisory sessions

Working sessions with your engineers on a live defect: pair on traces, reproduce in staging, or design a guardrail test.

Scoped implementation

When the remedy is clear, we implement a bounded patch — migration script, retry policy, or test harness — with handover notes.

Office workspace with monitors lit in a modern office environment

Who this is for — and who it is not

For: teams running revenue-impacting software who need a second pair of eyes on stubborn production defects, memory leaks, queue backlogs, or release pipelines that fail only in prod.

Not for: greenfield product design, generic staff augmentation without a defined fault, or requests to bypass security controls.

We work remotely with South African businesses and international teams comfortable with SAST-friendly hours.

Start with an inquiry

Scope, timeline, and fees are confirmed in writing after we understand your stack and the production symptom — never sold as an anonymous checkout.

Questions we hear on intake

Do you sign NDAs before seeing our repo?

Yes — mutual NDA is standard when source access is required. For high-level triage we can start from logs and architecture diagrams only.

Which languages and platforms?

We routinely work in mainstream backend stacks (Node, Python, Java, .NET, Go) and common cloud runtimes. The limiting factor is observability and reproducibility, not logo count.

How fast can you start?

Advisory slots depend on calendar; emergency assessments are scheduled when we have capacity and the fault is documented enough to be useful.